Saturday, November 17, 2007

Beware the Hail Mary Meta-Hyper-Framework

A while back I spoke with the CEO of a midsize enterprise software company. He invited me to work with a small team building a framework for customers to create applications that would run with his company's app.

I spent some time with the team, looked at the framework, and declined. As diplomatically as possible, I explained what I saw as the key problems with the initiative:

  • The term "architecture astronauts" barely touched these guys. I think they actually used the term 6GL in conversation. They were architecture hyperspace/time-travelers.
  • At the same time, I'd call them "infrastructure spelunkers" as well. The team trusted nothing, and was reinventing everything. They were rebuilding so far down the stack I started wondering where they built their own hardware. Then I realized that was silly -- after all, they would mine their own copper before they'd use someone else's wires.
  • The initiative had been running for several years with no concrete delivery. There was no deadline for a future delivery either. Given that the predominant tools and platforms were evolving underneath this team faster than the team was moving, I suggested I did not expect they would ever release.
  • No real world app -- either inside the company or among its customers -- was using it yet. That is, there was no dogfooding or validation of any kind that the framework was learnable or made the relevant problems easier to solve than existing approaches.

The CEO appreciated my frankness, and said that from his point of view, it was a big long-shot bet:

  • For him, the 15+ man-years that it cost to work on this framework were a non-issue. With plenty of revenue and people, if this initiative went nowhere, it would not be a significant loss to the company.
  • The framework was not critical-path for anything else, so he didn't anticipate any major downside.
  • Potential upside was, he felt, huge. If this framework somehow succeeded, he could grow his company much faster than he could any other way he could envision.

Well, I thought, I wouldn't make the same choice -- I would probably look to gain the same leverage using a radically simpler framework or mechanism -- but then I wasn't looking to take on an executive role, so it wasn't really my call.

DHH, the man behind the Rails web app framework, wrote about frameworks when he explained "Why there's no Rails Inc":

"... Rails is not my job. I don't want it to be my job. The best frameworks are in my opinion extracted, not envisioned. And the best way to extract is first to actually do. ... That's really hard if your full-time job is just the extraction part since you now have to come up with contrived examples or merely live off the short bursts of consulting. For some that might work, but I find that all my best ideas and APIs come from working on a real project for a sustained period of time."

Nicely put.

Wednesday, November 14, 2007

"Wrong Date" Emails == SPAM

On a regular basis, I get emails from vaguely reputable entities (airlines?!) sent with the wrong date. For example, on Wednesday I'll get a message "sent" on Monday. Because these messages show up out of order in a mail reader, and are marked "unread" among mostly "read" messages, they catch my attention. And sometimes I read them.

It's time to call this out for what it is: an annoying spamming technique designed to try and get my attention. And, like sending all your email flagged "High Importance," it gets old fast and makes you look bad.

There are plenty of time servers on the net. Plenty of bulk mailing mechanisms that don't get several days behind in getting the mail out. And plenty of docs on how to leverage UTC and offsets in your environment of choice.

So I don't believe anymore that a "misconfigured server" or "backed up bulk remailer" is to blame.

If I were an ISP, I'd think about creating spam filter rules that tweak an entity's rating every time bulk mail comes through with a date that's way off. Do this enough, and your messages go to my users' filtered spam folder.

Android? Give Me a Call When (If?) Phones Go On Sale

In this era of cluetrains, agile, getting real, perpetual beta, and all the rest, I would have thought that FUDly tactics like announcing big game-changing vaporware just to assert your position couldn't be taken seriously.

Not that Google's Android phone software is vapor (you can download it today) -- rather, the proposition of a viable phone ecosystem (devices, carriers, software -- in short, something you can actually use) is vapor.

It pains me to write this. After all, I proposed an platform-oriented MVNO (which Google may become with its possible spectrum bid), and I also stated that, to change the game, Google should support J2SE (and more), which Android does. And Google's challenging the carriers, who are the big problem in wireless software.

But I gotta call it like I see it, and announcing a big platform initiative when the first real handsets are at least a year away is a movie I've seen before.

There's an ALP announcement like this every six months; Palm announced the mythical Cobalt (with SDK!) over and over; Motorola made a big deal about its Linux phones. To be fair, Moto does ship a number of phones running Linux under the hood. But they're not really open, and neither developers nor consumers have taken much note. In early 2006 we were told MIDP 3 devices would be shipping by, er, now. Oh, and Sun's magic wand is going to bring us JavaFX mobile devices.

It's old-school (bad!) tech marketing at its worst. At best, these announcements need a bogo-coefficient to convert, say, "Just 12 months away!" to "Just 36 months away!" ... but really it's best not to believe in anything you can't buy at your local Sprint store.

Producing the SDK for public consumption now is not necessary to provide development lead time (how long did it take developers to build apps for the iPhone?). Plus freezing APIs now just makes it that much harder to alter the them when unforeseen issues crop up closer to mass production.

Although Apple is famous for taking a haughty approach toward their developers and customers, there is something to be said for putting the hardware and carrier together first, releasing the phone second, and then when you see what people really want to do with it, release an official SDK to help them.

I wish Google the best of luck with 700MHz, the carriers, the handset makers, the FCC, and the public. I'm just not sure this is off to an auspicious start.

Sunday, November 11, 2007

Agile Clients Present Challenges for Fixed-Price Consulting Firms

As more companies adopt agile development techniques, their increased desire for flexibility is causing pain for fixed-time, fixed-price consulting partners who have not yet figured out how to make the new dynamic work.

Traditionally, there are two models for technology consulting: "Time and Materials" (T&M), where the consultant bills per unit time and is only minimally responsible for the overall timeline, and "Fixed-time, Fixed-price," where the consultant is responsible for proposing a combination of scope, budget, and timeline and then delivering it.

The problem is that the initial time and price estimation models are based on a particular deliverable target. And while it's traditionally been a consulting challenge to keep change under control during an engagement, now clients are being completely upfront and saying, "We are developing alongside you and we intend to make substantial changes to the target every month, as the project develops."

With agile methods, this is not a shocker. And the client is justified in believing that if their organization can deliver new features and make spec adjustments every few weeks, surely high-priced consultants should be able to keep up.

The good consultants can keep up. The problem is figuring out a way for them to get paid for it; otherwise they won't be able to do these kinds of projects for long. Without a model that specifically addresses the possibility that expensive goal changes may arise, the consultants are forced into (a) being less agile than the client, (b) eating the cost of the changes, or (c) asking for more money or time. None of these options are good ones for the consulting relationship.

A first step toward a solution is to change agile co-development from an externality to a core part of the service delivery model. An iteration length should be defined as part of the project work statement. So far so good. The tricky part is allowing the consultants to make time or price changes at the checkpoints between iterations. After all, wasn't this whole project sold as fixed-time, fixed-cost? Sounds like having one's cake and eating it too. The reality is that both parties need to allow these changes (the client needs to change the specs; the consultant needs to change the cost) in order for the process to work.

The problem on the client's end is that development methods like agile, even if they tie in to product development processes, are often more "micro" in the budgeting scheme than the department budget or consulting budget. That is, the client's finances are not as agile as their development.

On the consultant's end, if the engagement is renegotiated -- even at a micro level -- between iterations, the overhead of managing and selling the project goes through the roof. And of course it's always possible that agreement can't be easily reached to match a spec change with a cost change. In that case, the whole engagement can fall though adding massive risk to delivery and reputation all the way around.

While not a complete solution, a number of elements would be helpful

  • Guidelines that throttle the rate of change between iterations via specified metrics, so that both sides have some ability to predict cost
  • Escalation chains for approval based on the amount of money or time involved, so that small and large changes alike don't necessarily need to go to a VP Finance or the legal department every time
  • Emphasizing these agile mechanisms in the sales process, so that an agile consulting firm (which might potentially cost a little more) remains competitive with others (who might offer a lower price but not be able to speak to how they will deal with these issues).

At this time, technology consulting opportunities abound and make good sense for clients and service providers alike. But to succeed in the long term, fixed-cost consultants need to evolve their models a few steps to keep up.

Sunday, November 04, 2007

Red Pill Shoe #2

So XSpace is actually, well, everyone in the social networking space except for Facebook.

And the Red Pill app itself is still a hypothetical, but it's getting closer and it's clear where that data would be helpful now.

Scoble's suggestion that his friends would all have to move before he'd look outside the "walled garden" of Facebook, and Don Dodge's suggestion that Facebook users won't just leave are both missing the point.

Users don't need to make up their minds now, they only have to decide that at some point in the future they might want to spend more time somewhere else. That's where Red Pill and its data come in.

Meantime, Bebo's press release headline ("[...] REVEALS PLANS TO LAUNCH FACEBOOK-COMPATIBLE DEVELOPERS PLATFORM") appears to overreach the actual article content -- namely, that Bebo will "make it easy for Facebook developers to port their applications," not necessarily host Facebook apps directly.

But there seems to be no clear reason why an OpenSocial proxy system could not actually host F8 applications. Except for maybe some terms-of-service issue. All those "fb" abbreviations and tags may have to get ROT13'ed or the like.

Saturday, November 03, 2007

Want a Real Cheap, Real Usable Windows Laptop? Don't Stop at XP, Go All the Way With Windows Server

As we move from back-to-school shopping shenanigans into holiday shopping shenanigans, a number of retailers (Wal-Mart, BestBuy, CompUSA) are selling dirt-cheap underpowered Windows Vista laptops for $300-$400 from vendors including Toshiba, Acer, and Gateway.

A few articles have been published on "upgrading" these machines from Vista Home Basic, which is more or less unusable on them, to XP Home or Pro. But why stop there? If you want to get down to business on a dirt-cheap laptops, and Linux isn't your thing, take a look at Windows Server.

I've used Windows Server 2003 on extremely old boxes (Pentium 3, 500 MHz, 384MB RAM) for testing and development purposes, and these machines are snappy. Server has a lot less eye candy and overhead than XP (I often catch it idling with only 120 MB of RAM in use), which makes it ideal for these underpowered machines.

How do you do the "upgrade"? Well, the the biggest challenge is the same as with XP: the laptop vendors provide Vista drivers only, and you'll need a Win2000-XP era driver for Server 2003. So before dropping the cash, do some research and make sure you can find XP drivers for the video card (on-board or not), Ethernet, and WiFi devices at the least. Sound card support can be hard to find too.

Once you've got the drivers, it's a straightforward install. Throw in another GB of memory (these laptops are sold with 512MB) for $30 or so, then go into the system control panel, boost the virtual memory setting and tell Windows to prioritize console apps rather than services (Server does the opposite by default, as one would expect). You probably want to uninstall the high-security mode of IE, if you're planning to use IE at all. Do this under Add/Remove Programs, and then Add/Remove Windows Components.

There are a small number of applications that can differentiate the server from the desktop Windows OSes and will complain (Grisoft's free AVG anit-virus product, for example, as well as some Windows Live apps). For the most part, though, all of your applications will run fine.

Now ... where to find a Server 2003 license? (The OS requires activation like XP.) At $999 for "Standard Edition" and $399 for the cheaper "Web Edition," this OS was never meant to be used with a $300 laptop. Although it would be nice if Microsoft offered a single-user non-server price, that's about as likely as Apple selling you MacOS for your Acer laptop. Good bets are companies buying new licenses of Server 2003 R2 or Server 2008 to replace Server 2003. You'd be surprised what unused or retired licenses could be kicking around your own company.

Another approach is to download the Server 2008 Beta and try that. 2008 is based on the same kernel as Vista, and so should use Vista drivers rather than XP drivers. However, I haven't used Server 2008, and I don't have any immediate experience that would inform performance, installation on random hardware, etc.

While this is not a recipe for building a cheap laptop for your less-than-computer-savvy relatives, if you're already a hacker looking for an extra portable machine to do Windows work on, it's almost certainly the most bang-for-the-buck possible.

Wednesday, October 31, 2007

Facebook Conundrum: Will it Tolerate a Red Pill Application?

Suppose I build a skeleton social networking app, call it "XSpace" for convenience. Maybe it has a couple of clever, unusual features, but there's nothing much there, and no users.

Now I build a Facebook application called "Red Pill."

If you add the Red Pill app, and give it permission, it will export data from your profile into storage on XSpace. None of this data is published or shared or anything else that would violate the current Facebook TOS. In fact, at this stage, it's a lot like FriendCSV, a current friend data exporter app -- it's actually a strict subset of FriendCSV, since the data is not actually downloaded as a file, just stored in a private spot in XSpace. (The FB Terms of Service prohibit storing user data for more than 24 hours, but this is less of an issue than it seems: we'll talk about this later)

Now I add a feature to Red Pill called "Take Me"

Take Me brings you into the XSpace app, with all of the social graph structure already in place, from everyone who has installed Red Pill, even if they've never "taken" it.

If a lot of people run Red Pill, then the core value of Facebook -- the network itself and to a much lesser extent the profile data -- is replicated into XSpace.

What happens next?

In the Facebook-success scenario, XSpace becomes an interesting alternative world to Facebook, linked by Red Pill "tunnels," and mirroring some parts of the social graph. Maybe a nice symbiosis evolves or XSpace is subsumed into a pure traditional Facebook app.

In the Facebook-failure scenario, something kicks off an exodus from the 'book. Whether it's a change in functionality, rules, service level, or just "cool factor," a mass of people pop the Red Pill and just start logging into XSpace instead. They keep all their original friend and profile data, so it's a smooth transition. Maybe XSpace also implements the Facebook API (it's a small, public API after all) so that Facebook apps can run in XSpace as well...

It is only a matter of time before the "Red Pill" and "XSpace" show up. That's the risk you take building a platform with a API -- it's actually to be expected, even desired.

But in the world of network-effect applications, there's a twist: these apps do not derive their value from being "the best implementation of the platform" (typically the way a platform implementer tries to assert value). Instead, the value is page views driven by the social graph itself and by the apps on the platform. Since both of these areas can be trivially replicated in XSpace, there's not much left. That is, there is no core value-add (aka Sustainable Competitive Advantage) left to Facebook as such.

Could Facebook cut off (or dial down) the API? Sure, but at the risk of slower growth and possibly aggravating users and developers who might like to play in someone else's open sandbox. And if they were too late in doing so, the move could actually spark the emigration to XSpace.

Could Facebook assert intellectual property rights over the data? Maybe, but facts cannot be "owned" as intellectual property. So the fact of my having a friend relationship to someone, or having met them in a class, or being married, are all things that no one owns. There is some user-generated content that the user has "signed away" rights to, but we're not talking about that. I.e., we are not proposing scraping out and re-using any content outside the core profile facts (age, name, etc.) and social graph.

Could Facebook complain about XSpace storing user data more than 24 hours? Maybe, but it depends on how the boundaries of the systems are defined, and in any case the better solution is for Red Pill to pull updated user data every 24 hours rather than archive the old data. If the app is ever cut off from retrieving this data, then it will keep the last snapshot, and then who cares, 'cause it's "game on."

As long as Facebook's valuation can be reinterpreted as an artifact of a Microsoft marketing expenditure (i.e., not a true investment, as some have suggested), this doesn't matter to anyone except maybe Microsoft.

But if Facebook is looking at taking really big money in, or eyeing an IPO, they'll be forced to think about cutting some of the Matrix exits. What will they do? What can they do?

Monday, October 29, 2007

Gratuitous Post: Gmail + IMAP = Sweeeeeeet

Ok, this is neither news nor particularly clever-monkey opinion writing.

But Gmail has been opening up full IMAP access on accounts, and it is truly a beautiful thing. Web mail is fine when it's all you've got, but whether it's stripped down (Gmail, old Yahoo! interface, etc.) or supa-deluxe JavaScript (new Yahoo!, Hotmail, er, I mean Windows Live) it can't beat the smart client.

And email clients are the original smart client: rich client with offline capabilities + access to network resources.

I'll still use the Gmail web interface sometimes, so it's not like Google won't get a chance to present me with plenty of ads, but having access from Outlook and especially Outlook Mobile on my Windows smartphone (sorry, guys, it just works better than the J2ME Gmail client) is absolutely killer.

I didn't think the free-online-email game was going to change a whole lot at this point, but this is a game-changing move by Google.

Microsoft Will See Your Web Services and Your Horizontal Database Scaling, and They'll Raise

Don Box has come out in defense of Microsoft's support of REST technologies a number of times. And this year we've started to see what else is behind the curtain, with project Astoria. Still being designed and built, but with bits available and integrated into VS2008 today, Astoria includes both local (your own machine/datacenter) and cloud services for data storage that support HiREST, relational modeling, and support for various data formats (JSON, POX, Web3S [the last a play on, and jab at, S3?], ATOM).

If you haven't seen these services, you need to check them out. In addition to being technically interesting (e.g., since queries can be expressed via REST-style URLs, your network appliances and front-end web servers can actually participate in execution or caching strategies!), these services are likely to be a big part of the web service landscape.

Whether you love Microsoft or not, it is fairly clear that the original ASP.NET SOAP implementation (and client generation) were years ahead of anyone else in terms of no-nonsense ease of use, compatibility, and extensibility.

These SOAP components were made available to developers in 2000 or earlier. They brought things like "Type [WebMethod], ok now you have an XML-RPC SOAP service. You're done, go home, have a beer," while Java was still trying to figure out how which alphabet to jam into the end of their JAX* wildcards, and inventing APIs where you just start off with a nice ServiceFactoryBuilderConfiguratorFinderInstantiatorFactory and go from there.

Why rehash this history? Because in its final form, the Microsoft solution is going to be influential. They may be late to the party here, but don't discount them.

Enterprises need service description layers for REST. Someone is going to give it to them in a way that they can use it. And an Amazon-S3-scale relational data service in the cloud (no, Freebase and the like don't count) could be really interesting to everyone who doesn't have enterprise, need-my-data-physically-in-house requirements. With ActiveResource a core part of Rails 2.0, I could see building read-heavy apps using caching and Astoria, and no local database at all! My clustering problems (and expense) have all just become someone else's problem!

There's something else to see here too: read the Astoria dev team blog and the comments. You're watching Microsoft designing and implementing a big API in real time with interaction from the community. Don't look for an open-source experience -- you can't check out the code and send patches. But there is a lively discussion going on between the development team and outsiders to try and come up with the best solution that fits the constraints.

Tuesday, October 23, 2007

Clowns on Parade: Giving Administaff Your Keys Isn't Much Better Than Leaving the Door Open

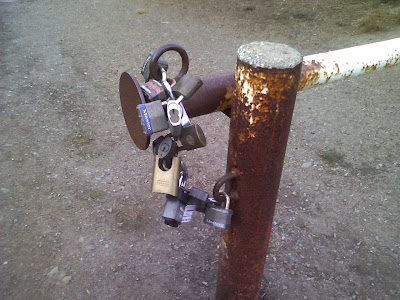
Chains and their "weakest links" are used all the time in metaphor. But I realized this metaphor was wrong after seeing an odd "chain of locks" securing a no-vehicle gate last week near the GGNRA in Marin.


The only practical reason I could imagine for using this chain of locks is that a large number of people all need to be able to open the gate (e.g., park staff, firefighters, police). Instead of having one lock and sharing copies of the key, someone decided to give each party a lock and key. By chaining them together, any opened lock allows the gate to be opened.

I'm still not sure why they would choose this approach (if any reader is familiar with this construct, please tell me!)

With personal information, we may not share a "master key" with many people, but we offer a lot of locks and keys to a lot of different parties. Any one of them can leave us wide open. Like last week, when Administaff -- a huge co-employment organization that my employer uses -- announced ... (drumroll) ... a laptop was stolen with personal info, including SSNs, for everyone on every payroll they processed in 2006 (approximately 159,000 people total).

With friends like this ... you know the rest.

There's a wonderful FAQ on the theft, where Administaff explains that it's not the organization's fault: "the information was not saved in an encrypted location, which is a clear violation of our company’s policies." In other words, they're blaming the employee for violating the company policy.

I don't buy it.

Yes, I believe there's a company policy somewhere that says not to copy the entire human resources database onto your laptop in plain text.

But I don't believe Administaff made reasonable efforts to see that this policy would be carried out.

I suspect there were at least three distinct failures:

Failure #1: The employee whose laptop was stolen was tasked with an activity for which the easiest workflow involved loading the entire database onto his or her laptop. How do I know this? Most workers do not take the hardest route to doing their job. They take the easiest one they can.

In this case, someone took the easiest route even though it meant violating a policy (that he most likely never took note of anyway). When Administaff management allows the easiest workflow to be one with this much security exposure, they share the blame. If they don't know what workflows are being used for Social Security data, then they are failing at a bigger level, namely not auditing sensitive processes in their own identity-theft-prone line of business.

Failure #2: At best, the server system which "owns" the stolen data allowed this employee to produce a report containing critical data for a very large number of records. (At worst, this data is not stored in any controlled application at all, but rather in something like Access, FoxPro, or Excel. While I know this is a real possibility, it's such a revolting idea that I will ignore it for now.) Assuming this application has a user/role model, why would this user have such a reporting privilege?

Even if the application is designed to support some "work offline" workflow, so a that network connection is not required to access each record, this can be accomplished without any mass download of records. A modest number of records could be downloaded and cached for an offline work session, and synched back later. The record cache would, of course, be secured with a passphrase and/or other elements.

My point here is that there's no way the employee accessed and then copied/saved each of 160,000 records, one at a time. The application had to help, making it easy to do some operation on "all" or on a large set of records (birthdate in a specific year, last name starting with a certain letter, etc.) Awful idea. Administaff is leaving the door wide open, no surprise that the employee stumbles on through.

Failure #3: How long was this data on the laptop before the laptop was stolen? At one large financial institution, any computer connected to the network -- whether on site or via VPN, virtual machine or real -- was subject to regular scanning from the mother ship. The security group would check all of these machines not only for vulnerabilities (viruses, vulnerable services), but also for content. Were they after pr0n? Not so much. They wanted to find out if any disproportionate amount of their data ended up on any of your machines.

If, say, they found a file that looked like a bunch of credit-card numbers, you'd have some explaining to do. While this approach would not stop a clever data thief (who would employ steganography or removable drives), it would do a great job at stopping any accidental hoarding of customer data. In fact, it would do a great job at stopping this pervasive stolen-laptop-stolen-data problem.

Apparently Administaff really cares about this stuff. Surely enough to spend the half-hour thinking about it that I did when I wrote this post. Just not enough to actually do anything.

Thursday, October 18, 2007

Double Black Diamond Software Projects

I've spent a good part of my career working on particularly challenging development gigs that I have come to call "Double-Black-Diamond Software Projects"

What exactly is a double-black-diamond project?

The name comes from ski trail markings, where a single black diamond indicates (at least in the U.S.) an "advanced" trail, while two black diamonds indicate "expert."

In reality, the difference between single- and double- black trails is that a strong skier can typically waltz onto a single diamond slope and have confidence that it may be interesting or challenging, but it will have a predictable outcome.

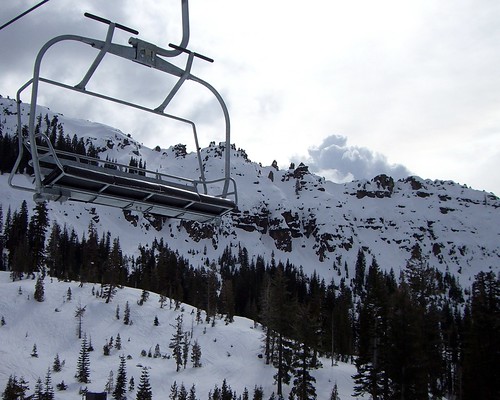
The double black trails, on the other hand, can feature hidden obstacles, cliffs, terrain features that vary with the snow conditions, and even areas which may be practically unskiable depending on conditions. (E.g., the cliffs in the background of this image are the double-black "Palisades" at Sugar Bowl.)

In software development, a double-black-diamond project is one where the outcome is in question from the beginning, not because of resource issues (e.g., too few developers or too little time), but because some fundamental unknowns are involved. Something new is being created, and it is sufficiently unique as to make it unclear whether it is even possible to succeed, or exactly what "success" will look like.

These unknowns might involve integration to an unknown external system, performance of problematic features like voice recognition, custom hardware, etc. If these challenges seem feasible enough, or success seems valuable enough, to make the software project worth a try (ultimately an investor decision), but the sheer implementation risk (as opposed to business risk) is clear from the start, you've got a double-black-diamond slope in front of you.

I will be writing a number of posts on these double-black-diamond software projects, and I plan to cover
  • typical elements ("signposts") indicating a double-black project
  • why, as a developer, you might ever want to get involved in such a project when there are lots of other opportunities
  • gearing up: the skills, knowledge, and/or people to bring with you
  • the art of keeping project sponsors properly informed (the subtle part is the definition of properly)
  • how to handle risk and predict outcomes (as much as possible)
  • maneuvers and techniques to gain leverage and minimize the odds of failures or surprises
  • managing the definition of "project success" (and why it's essential to do so, even as a coder)

Wednesday, October 17, 2007

Mozy Keeps Your Data Safe ... Once You Get It Working

A while back I wrote about Carbonite, a consumer PC online backup solution. I thought the user experience was fantastic, but I didn't love the idea that my data could be decrypted with just my (low-entropy) site password.

More recently, I decided to give Mozy a try. Mozy is another leading online backup app, and they offer 2 GB of personal backup for free. Interestingly, Mozy seemed to me to have the opposite qualities (both positive and negative) as Carbonite in my trial.

The security is hard-core if you choose: Mozy generates a 448-bit encryption key from any chunk of text or file that you give it. Naturally that means your source should have some decent entropy in it, and you'd better have a copy of either the key source material or the generated key file if you ever want your data back. But the folks who really want to keep their own key will know this already.

Mozy does encryption (and presumably decryption in a restore) locally, and ships the encrypted files off to storage. So your data is pretty darned safe from anyone inside or outside of Mozy.

The "average user" experience, though, had a number of annoying snafus.

The GUI on the client tool that manages your backups and filesets is neither pretty nor intuitive. I'm tempted to compare it to some of the more mediocre Gtk front ends to Linux command-line tools. Perhaps that's too harsh, but it does have a number of similar quirks, like multiple widgets that control the same setting without being clear about it, checkboxes becoming checked or unchecked "on their own", etc.

More troubling was that the client appears non-robust in the face of network outages. When the network dropped during my initial config, the app crashed. Upon restart, it did not appear to have saved state: I had to redefine my backup sets. I then started a backup, and the app crashed again when the network momentarily dropped. This time when I restarted it did have my backup sets, but the history window showed no trace of my failed backup.

Then, during my next backup attempt, after getting several hundred megabytes onto the net, my machine rebooted itself (courtesy of a Microsoft "patch Tuesday"). When I looked at Mozy, its history again showed nothing. I would have liked some information about the failed backup, and a way to "resume." Instead, I had to start the whole backup from byte 0.

This latter time, I achieved success. But in an era of WiFi access (which can be flaky), I would expect not only robustness in the face of network connectivity issues, but also a really solid resume mechanism. After all, how many machines will succeed with the initial multi-gig upload in one go?

To finish on a positive note, I should point out first that for paranoid^H^H^H^H^H^H^H^H security conscious people, it's great to have a tool that handles strong crypto inline and gives me control over the only key. Also, a quick search suggests Mozy is ready to bring out the heavy guns to address customer problems. If they keep that up, they'll be able to overcome almost anything else.

Thursday, October 11, 2007

Thanks for the Wakeup Call! Jeff Atwood Explains Why I Shouldn't Write a (Traditional) Book

Jeff Atwood's Coding Horror is one of my favorite blogs.

He recently wrote about his new ASP.net book, and instead of telling everyone to go buy a copy, he spent his words explaining why one should not write a technical book.

To summarize, he pointed out
  1. The format and process was painful to work with
  2. "Writing a book doesn't pay"
  3. One shouldn't associate any extraordinary credibility with publication. Jeff's a little more blunt: "Anyone can write a book. ... The bar to publishing a book is nonexistent..."
  4. "Very few books succeed ... In the physical world of published atoms, blockbusters rule" or, in case you forgot the pre-web-2.0 world, the long tail isn't supported by the economics.
These arguments hit home with me because I had been preparing a book "proposal proposal," and chatting with some publishers (I say "proposal proposal" because a proper book proposal has a certain form and content which I have not fully developed; what I have is a more informal proposal; i.e., a proposal for a full proposal).

At a certain level, I already knew I am living in the wrong decade for the dead-tree book. But I also imagined that, since my topic is a little bit more process- and project- oriented, rather than "how to write an app with the new foobar 3.0 API," my book might have more long-term relevance or staying power.

But Jeff's post hit me like the knocking at the door in Macbeth. He's right. At the end of the day, the publisher and bookstores are not going to do anything impactful to promote my book; it will be hard to find on a shelf with 1500 tech books that change every 3 months, and I wouldn't expect it to sell remarkably well.

My main goal in writing is to share some knowledge and experience with folks who are interested and who might benefit. And writing and publishing online, I have a lot of confidence that my audience will find my content.

This belief comes from looking at the web analytics for my blog: through the magic of Google, I get solid traffic for meaningful keywords. For example, my post on the .net implementation of J2ME hidden (?) in Y!Go, but which you can use to port your own MIDlets to Windows Mobile, is result #8 (today) if you Google "j2me .net implementation" ... and it drives a bunch of traffic.

That's good enough for me.

Now I'm realizing that there are no advantages to the legacy tech book publishing process for me (I'm sure that for established, famous authors who write for a living, it's a different story). But there are a lot of advantages to avoiding that publishing process. Beyond the simple advantages of being accessible via Google, etc., I will surely save an enormous amount of time interacting with the machinery of the publishing industry.

Time saved is time I can spend writing and refining my core content. And if it's not perfect, that's ok, because there's no offset printing and physical distribution. I can fix typos or code errors instantly. I can revise and re-post if I realize I've said it wrong. I can offer old versions if anyone cares to see them.

Meantime, if anyone wants a printed and bound paper copy, there's always lulu.

Thanks, Jeff!

Wednesday, October 10, 2007

Project Manager as Diplomat: Herald or Negotiator?

If software project managers are diplomats -- and I think most project management roles see them this way -- then there are at least two distinct flavors: heralds (low level diplomats) and negotiators (high level).

The difference is sometimes imposed by the project/work situation, but more frequently appears to be self-imposed by the project manager.

The herald project manager sees his or her role as a courier bringing messages back and forth between various parties. The parties may be friendly or hostile, and the communications may be straightforward, complex, or threatening. But if the herald gets the info to the recipient in a timely way, his job is done and he expects to pass unmolested.

The negotiator project manager, on the other hand, sees his role as keeping everyone on the same page about decisions and outcomes. If (when) parties are not in agreement, the negotiator tries to bring about sufficient discussion and confrontation that something can be agreed upon.

The project manager rarely has direct authority over multiple parties in the project (e.g., engineering, product management, and marketing). He can, perhaps, control one closely aligned party through resource allocation. In general, though, I've seen more of a carrot-and-stick approach:

The PM has opportunities (e.g., a recurring meeting) where he holds the floor and escalates all of the known issues, so that everyone is painfully aware of the potential problems. He then reminds everyone of all the negative consequences coming down the pike for the project, if key decisions and compromises are not made. He also points out how well things will turn out for everyone if the project can reach completion on time, on budget, and with everyone more or less happy with what was done.

With enough persistence, it is usually possible to keep things on track. How? The negotiator's secret weapon in the business arena is his willingness to make people consider negative possibilities that they are not likely to raise on their own, and to make it seem matter-of-fact. Business groups (at least in the U.S.) are extremely uncomfortable thinking about and planning for negative outcomes. So the project manager gets to make a whole room full of normally confident people very uncomfortable. In order -- literally -- to alleviate this discomfort, they start to talk and become a bit more flexible.

It is clear that the negotiator PM is doing the heavy lifting, while the herald PM is a glorified secretary. The herald may be useful in a large project where so much information is flying around that it's worth having full time staff to keep it straight. He's holding off entropy but not solving big problems. The negotiator feels like his success depends on getting people to work together for success, which is a bigger challenge and produces bigger rewards.

When you are choosing, hiring, or staffing project managers for software projects, keep this dichotomy in mind. Unless your world is all rainbows and unicorns, you probably need a negotiator, and getting this sort of PM will pay off handsomely. You can supplement him, if the project is really big, with a herald PM to "do the paperwork."

But if you enter a challenging project with nothing but a herald PM, you are increasing your project risk considerably.

Tuesday, October 09, 2007

Writing Javascript on a Phone, on a Phone

I'm on vacation, so I'm writing some less, um, in-depth posts. Hopefully. Like this one:

I've gotten bored waiting in lines, on airplanes, etc., and I thought it would be a fun way to waste time if I could program my phone.

I wanted to be able to do it without a PC, just with the phone itself. And I didn't want to do it over the network (i.e., edit some code, send it off to a web page or network app to compile, run, etc., and return results, even thought that could be a fun way to tinker when you're on a good connection).

I thought there must be some kind of compiler or interpreter for my Blackberry or, now, Blackjack. And yes, I know, if I had a real Linux phone, then I could just download any tools I wanted. But Linux smartphones with QWERTY keyboards are hard to come by.

Enter Javascript.

I used to hate Javascript. A whole lot. Then I watched Douglas Crockford's fabulous lectures on Javascript, and it turned my whole attitude around. I realized I had never understood what Javascript was about in the first place. And here was a really smart guy who knew all of the problems, and didn't say "get over it," but talked about finessing your way to the true nature of Javascript. Which, incidentally, are lambda expressions. Crockford asserts that Javascript is more or less the only "lambda language" to organically receive mainstream adoption in the development industry.

Now I only hate the browser hosting environment for Javascript. And with enough plug-ins, even that isn't so bad.

Since Pocket IE has Javascript support, and I can edit text files and save them on my phone, I can build up a library of the functions that do what I want, and this library becomes the web page that I run and hack in with PIE. This is where having a real smartphone, not a crippled one whose manufacturer tries to deny me access to the local filesystem, is helpful.

Goofy? Kinda. But it keeps me out of trouble.

Wednesday, October 03, 2007

One Reason Software Development is Such a Malleable Process

This post is the fifth (the others are here, here, here, and here) -- and last planned one -- summarizing and commenting on elements from Steve McConnell's excellent Software Estimation: Demystifying the Black Art.

At the beginning of Chapter 23, Steve writes:

Philip Metzger observed decades ago that technical staff were fairly good at estimation but were poor at defending their estimates [ ... ] One issue in estimate negotiations arises from the personalities of the people going the negotiating. Technical staff tend to be introverts. [ ... ] Software negotiations typically occur between technical staff and executives or between technical staff and marketers. Gerald Weinberg points out that marketers and executives are often at least ten years older and more highly placed in the organization than technical staff. Plus, negotiation is part of their job descriptions. [ ...] In other words, estimate negotiations tend to be between introverted technical staff and seasoned professional negotiators.
This is a valuable observation in estimation scenarios. It also reminded me of some hand-waving I did about 6 months ago in reply to a comment on this post. I wrote that the reason some industrial process control type procedures fail when applied to producing software is that "There are too many social vulnerabilities -- the software process itself is inherently 'soft' in a group dynamics sense, so it gets reshaped by the org's internal disagreements."

I stand by that comment, but it seemed a bit vague. I think Mr. McConnell's summary of the personalities that push and pull around software commitments is quite helpful. His description clarifies one of the software group's social vulnerabilities. After finding themselves agreeing to a problematic "estimate," engineering groups may be able to make up for their poor performance at the negotiating table by trying to "reroute power from the warp core" ... but we know that statistically, over the long term, that approach fails, leaving chaos in its wake.

What to do? A proverb says that a man representing himself has a fool for a lawyer. I.e., right or wrong, he is likely no match for a trained, experienced legal professional on the other side.

So let's get the software team some representation. Not a lawyer, but an executive advocate, someone with the personality and negotiation skill-set to go to the mat with other parties.

If this person has a good grasp of the technical issues, all the better; if not, he or she can take it offline and come back to the engineering team for a briefing.

Of course, if the engineering group somehow gets the impression that the representative has sold them out, making unauthorized or unreasonable commitments, then we are back at square one.

Sunday, September 30, 2007

In Software Estimation, Fewer Inputs Can Trump More Inputs. Here's Why:

This post is the fourth (the others are here, here, and here) summarizing and commenting on elements from Steve McConnell's excellent Software Estimation: Demystifying the Black Art.

There are estimation models that take a large number of inputs, and others that rely on only a few inputs. Some of the input data are more objective (e.g., the number of screens in a spec) while other data are more subjective (e.g., a human-assigned "complexity" rating for each of several reports).

One thing that Steve explains is that, when many subjective inputs are present, models with fewer inputs often generate better estimates than models with "lots of knobs to turn."

The reason for this is that human estimators are burdened with cognitive biases that are ridiculously hard to break free of. The more knobs the estimator has to turn, the more opportunities there are for cognitive biases to influence to result, and the worse the overall performance.

It should be reiterated that this same problem does not apply to systems that take many objective measures (such as statistics or budget data from historical projects) as inputs.

Saturday, September 29, 2007

Lifecasting will be Prevalent, and has a Down-To-Earth Future

Lifecasting is one of those things that is interesting on a theoretical, academic, political, and artistic level. Yet, right now, it's pretty boring in "real life."

But there is a big bourgeois, commercial opportunity coming for lifecasting, and with that will come low prices, ubiquity, and all sorts of new content also relevant to the avant-garde. In the same way that cellphone cameras now catch politicians off guard and police beating protesters, the surveillance (sousveillance?) society will take a quantum leap forward.

Walgreen's sells a low-end USB web cam for $14.99 today, and for well under $100 one can get a higher-end unit. I predict that in 2-5 years, I'll be able to drop $40 in Walgreen's and get a wearable cam/mic with an 8-ounce belt-clip battery that will plug in to my cell phone ... and I'm in the game with justin.tv.

This is not live-without-a-net futurism here, either. I'm making a modest argument by extrapolation on the hardware side. The original justin.tv rig was a hassle to put together with today's technology. The biggest challenges involved upstream mobile bandwidth, battery power, and data compression.

With EVDO Rev B, HSUPA, and WiMAX, bandwidth looks to be less of a problem than giving customers a reason to buy it. As MPEG-2 fades away in favor of MPEG-4 flavors like H.264 and 3GP, cheap hardware compression is already becoming less of an issue. In fact, many of today's low-end smartphones are most of the way there in terms of a basic lifecasting rig. Battery power will remain an issue for anyone wanting to go live 24/7. But for a few hours at a time, several ounces of lithium-ion will keep the camera, compressor, and radio humming.

So what are the bourgeois, commercial applications?

  • Conferences: organizers won't love broadcasts of the content, but, at least in tech, they are desperate to find some way to keep the shows compelling. I can see a lot of organizations sending one delegate to lifecast while others back home watch and interact, including talking to vendors, visiting hospitality suites, etc.
  • Meetings: an interactive lifecast of a remote meeting would be a more productive way to participate than just a conference call or even a traditional web/videoconference.
  • Social events: suppose your school reunion is far away and not nearly exciting enough to make the trek. But a friend who lives in the area goes, and you can ride along via lifecast? That could be a riot. And if it isn't, just close the browser.
  • Education: how cool would it be sit in on some virtual flight lessons, tuned in to a lifecast from a CFI giving a real student a real lesson.
  • Remote Personal Assistant: Instead of a worrying about wearable computers with smarts, you go about your business while a remote assistant tracks your lifecast. Need directions? a pickup line? a reservation? instant info on anything? Your assistant, sitting somewhere comfortable with easy access to all things cyber can do the virtual legwork and send you what you need in real time.

The monetization platform is already here, as early adopters have jumped out ahead. Phone hardware (which will serve as the workhorse for the system, just as it does now for millions of phone-cam snapshots, videos, and mms messages) is moving at a rapid pace. That just leaves a few more parts to design and sell to complete the picture. With the amounts of VC money flowing today, I don't see that last part as a problem.

Thursday, September 27, 2007

LOC Counts to Compare Individual Productivity? No Way.

"Measuring programming progress by lines of code is like measuring aircraft building progress by weight." - Bill Gates

The other day, someone on my project team proposed ranking developers by their lines-of-code committed in Subversion. I really hope the suggestion was meant to be tongue-in-cheek. But lest anyone take LOC measures too seriously, it's worth pointing out that LOC is a bad, bad metric of productivity, and only gets worse when one tries to apply it across different application areas, developer roles, etc.

Here are a few reasons why LOC is not a good measure of development output:

  • LOC metrics, sooner or later, intentionally or unintentionally, encourage people to game the system with code lines, check-ins, etc. This is bad enough to be a sufficient reason not to measure per-developer LOC, but this is actually the least bad of the problems.
  • LOC cannot say anything about the quality of the code. It cannot distinguish between and an overly complex and bad solution to a simple problem, and a long, complex, and necessary solution to a hard problem. And yet it "rewards" poorly-thought-out, copy-paste code, which is not a desirable trait in a metric.
  • In software development, we desire nicely factored, elegant solutions to a problem -- in a perfect world, we want the least LOC solution to a problem that still meets requirements such as readability. So a metric that evaluates the opposite -- maximum LOC for each task -- is counterproductive. And since high LOC certainly doesn't necessarily mean bad code, there isn't even a negative correlation to use from the measurement.
  • In general, spending time figuring out the right way to do something, as opposed to hacking and hacking and hacking, lowers your LOC per unit time. And if you do succeed in finding a nice compact solution, then it lowers your gross LOC overall.
  • Even in the same application and programming environment, some tasks lend themselves to much higher LOC counts than others, because of the level of the APIs available. For example, in a Java application with some fancy graphics and a relational persistence store, Java2D API UI code probably requires more statements than persistence code leveraging EJB 3 (based on Hibernate) based on the nature of the API. Persistence code using straight JDBC and SQL strings will require more lines of code than EJB 3 code, although it’s most likely the “wrong” choice for an application for all sorts of well-known reasons.
  • In the same application and environment, not every LOC is equal in terms of business value: there is core code, high-value edge-case code, low-value edge-case code. To imagine that every line of every feature is the same disregards the business reality of software.
  • You may have read that the average developer on Windows Vista at Microsoft averaged very few lines of code per day (from 50 down to about 5 depending on who you read). Is Microsoft full of lazy clueless coders? Is that why the schedule slipped? I doubt it. There were management issues, but Microsoft also worked extremely hard to get certain aspects of Vista to be secure. Do security and reliability come with added lines of code? Unlikely – in fact, industry data suggest the opposite: more code = more errors, more vulnerabilities.

But no one on our team would ever write bad code, right? So we don’t need to worry about those issues.

Not so fast… Developers, even writing “good” code, generally make the same number of errors on average per line (a constant for an individual developer). So if I write twice as many lines of code, I create twice as many bugs. Will I find them soon? Will I fix them properly? Will they be very expensive sometime down the line? Who pays for this? Is it worth it? Complex questions. Never an easy “yes.” Or, as Jeff Atwood puts it, “The Best Code is No Code At All.”

And beautiful, elegant, delightful code is expensive to write (because it requires thought and testing). The profitability of my firm depends on delivering software and controlling costs at the same time. We don’t fly first class and we don’t use $6000 development rigs, even if we might offer some benefit to the client or customer as a result. And we don’t write arbitrary volumes of arbitrarily sophisticated code if we can help it.

Ok, so why, then, is the LOC metric even around? If it’s such a bad idea, it would be gone by now!

Here’s why: while LOC is a poor measure of developer output, it’s easy to use, and it’s a (primitive but functional) measure of the overall complexity and cost of a system. When all the code in a large system is averaged together, one can establish a number of lines per feature, a number of bugs per line, a number of lines per developer-dollar, and a cost to maintain each line for a long, long time into the future.

These metrics can be valuable when applied to estimating similar efforts in the same organization under similar constraints. So they’re worth collecting in aggregate for that reason.

But for comparing individual productivity? I don’t think so.

Wednesday, September 26, 2007

Sun CTO: JavaFX Mobile Stack Aims to Clean up J2ME Disaster^H^H^H^H^H^H^H^H Issues

It's only mild hyperbole to call J2ME a disaster. If you've depended on ME to make a profit, it might not be hyperbole at all.

But good news may be somewhere in the pipeline. This morning I heard Sun CTO Robert Brewin speak at AJAXWorld. His talk largely concerned enterprise services, but when he mentioned that one argument in favor of Java is its ubiquity, and that Java runs on about two billion phones, I couldn't help but stand up and ask for the mic.

Since Robert was ready to acknowledge the existing hassles, my question was: does Sun plan to fix it -- e.g., by becoming more stringent about how devices are certified as Java-capable?

In his response, he punted on the J2ME aspect, suggesting developer could put pressure on device manufacturers to standardize their Java behavior. Since cellphone carriers are players in the equation, I'm awfully skeptical about that. But the cool part was that Mr. Brewin said that the place where Sun plans to really make an impact here is with JavaFX Mobile.

Since JavaFX Mobile, adapted from the Savaje Java-based OS acquired by Sun, is a full kernel-to-app stack, it should provide much better -- perhaps even 100% -- compatibility between devices.

Now let's keep our fingers crossed for full J2SE support on it.